Generative AI Development That Drives Real Business Growth
Generative AI has evolved beyond simple chat interfaces. Real enterprise value comes from private data grounding, autonomous multi-agent orchestration, deterministic guardrails, and customer experiences that build lasting trust.
At Nexovio Digital Solutions, we engineer tailored generative AI applications designed around your exact business logic. From high-converting customer experience copilots and RAG knowledge engines to autonomous workflow swarms, we deliver production-ready AI with measurable ROI.
Build Generative AI Systems That Customers Love & Trust
Adding an AI capability shouldn't feel like a disconnected experiment. A successful generative AI product requires tight integration with internal systems, verifiable knowledge sources, and an intuitive customer experience.
We bring AI engineering, UX design, and enterprise data security together under one roof, delivering robust systems that safeguard your brand while solving core business friction.
Grounding in Private Business Data (Zero Hallucinations)
We connect models to your actual enterprise documents, catalogs, and databases via hybrid RAG, ensuring all generated responses are verifiable with clickable source citations.
Customer Experience Designed for Attraction & Retention
Human-grade conversational interfaces built with low cognitive load, empathetic phrasing, instant streaming tokens, and graceful escalation to live human specialists.
Autonomous Multi-Agent Task Orchestration
Move beyond simple Q&A. Coordinated agent swarms handle complex multi-step reasoning, external API tool execution, and continuous quality audits autonomously.
Model-Agnostic Flexibility & Vendor Independence
Avoid vendor lock-in. Our semantic routing layer connects seamlessly to OpenAI, Anthropic Claude, Google Gemini, or self-hosted open-source models like Llama 3.
Deterministic Enterprise Guardrails & PII Masking
Automated security filters scrub customer PII before sending queries to models, while strict prompt injection shields protect against malicious system jailbreaks.
Continuous Telemetry, Spend Control & Latency SLA
Real-time monitoring of token consumption, cost caps, drift detection, and latency telemetry ensures predictable operation without unexpected monthly cloud bills.
We prioritize real-world utility over hype: reliable response times, zero unauthorized data sharing, low operational inference overhead, and software your team can comfortably maintain.
End-to-End Generative AI Development Services
Explore our specialized generative AI engineering capabilities, crafted for enterprise dependability, low-latency performance, and measurable business impact.
Custom Generative AI Applications
Tailored AI Applications Aligned with Your Proprietary Workflow
Develop purpose-built AI applications rather than generic API wrappers. We architect specialized enterprise workspaces, internal AI copilots, and multi-modal generative interfaces connected to your real business data.
- Custom role-based internal AI workspaces
- Interactive data synthesis and analytical copilots
- Multimodal prompt, image, and document handling
- Dedicated corporate sandboxes & privacy isolation
- Production Next.js / TypeScript application frontends
AI Customer Experience & Intelligent Assistants
Empathetic, Low-Latency Customer Interaction That Drives Retention
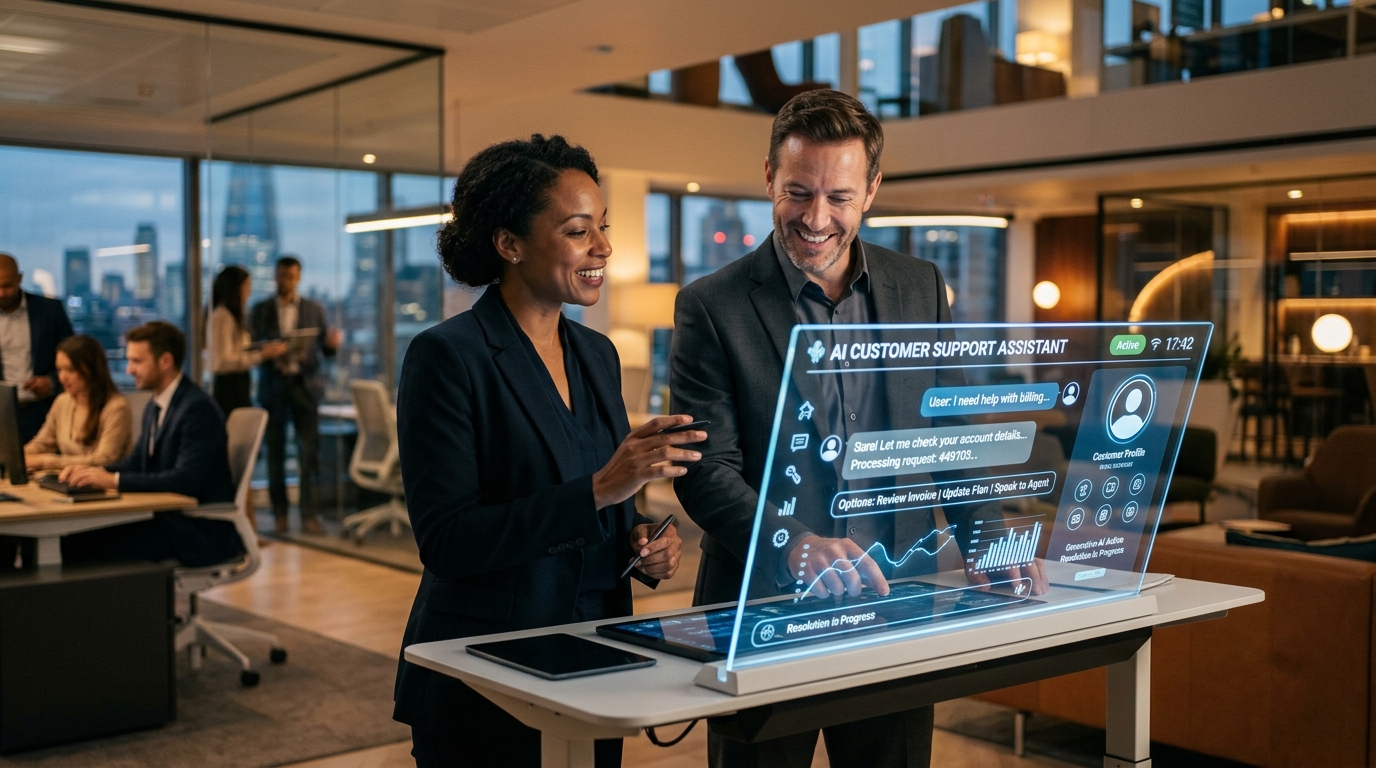
Transform customer engagement with context-aware, 24/7 generative assistants. Engineered with dynamic memory, sentiment calibration, sub-second streaming answers, and seamless escalation to human teams.
- Conversational customer onboarding & discovery
- Omnichannel chat, voice, and helpdesk integration
- Dynamic tone-of-voice alignment with brand guidelines
- Instant, verified knowledge-base dispute resolution
- Smart sentiment routing & zero-friction human handoff
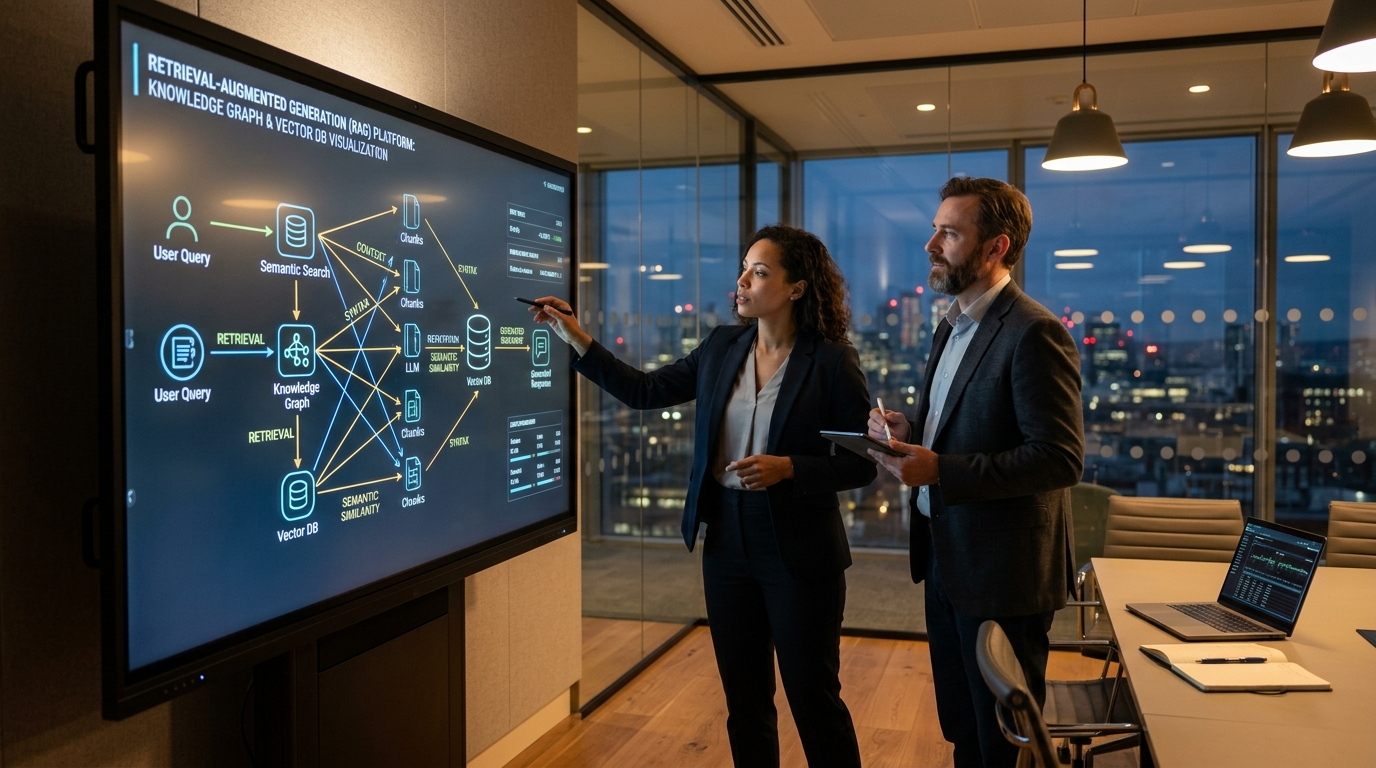
Enterprise RAG & Knowledge Retrieval
Ground Foundation Models in Private Corporate Data Securely
Eliminate model hallucinations by retrieving precise facts from internal documents, PDFs, manuals, and databases before synthesis. We implement hybrid semantic vector search with real-time citation links.
- Semantic hybrid vector search (Pinecone, Qdrant, pgvector)
- High-accuracy document ingestion & chunking pipelines
- Exact source citation & verifiable reference footnotes
- Enterprise access control & document-level security
- Sub-300ms vector retrieval cache architecture
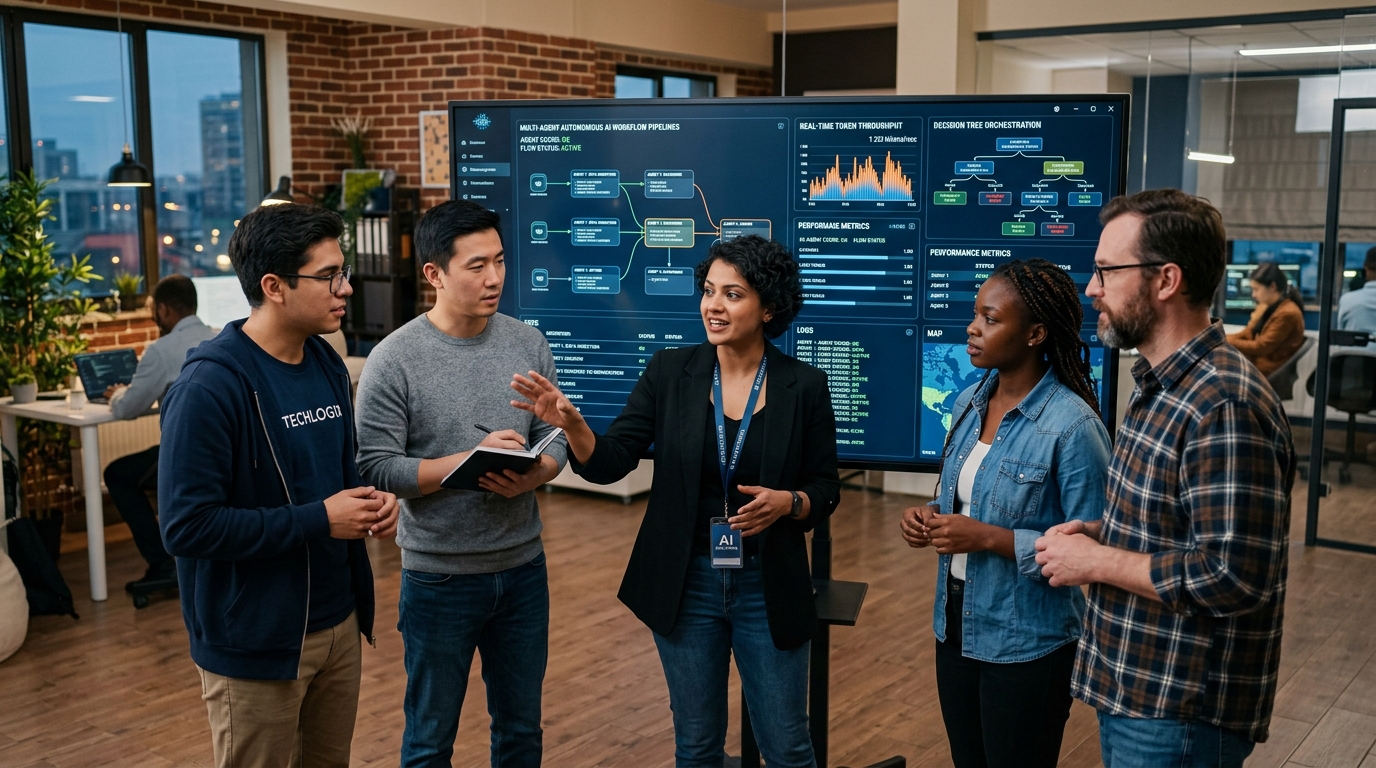
Autonomous Multi-Agent Workflow Pipelines
Goal-Oriented Agent Swarms That Reason, Execute & Audit
Deploy coordinated teams of autonomous AI agents capable of planning, executing complex multi-step tasks, calling external REST APIs, querying databases, and auditing their own results with supervisory guardrails.
- Specialized agent roles (Researcher, Planner, Executor, Auditor)
- Tool-calling integration with CRMs, ERPs, and cloud APIs
- Self-correcting feedback loops & iterative reasoning
- Human-in-the-loop approval thresholds for high-stakes actions
- Real-time token telemetry & execution trace logs
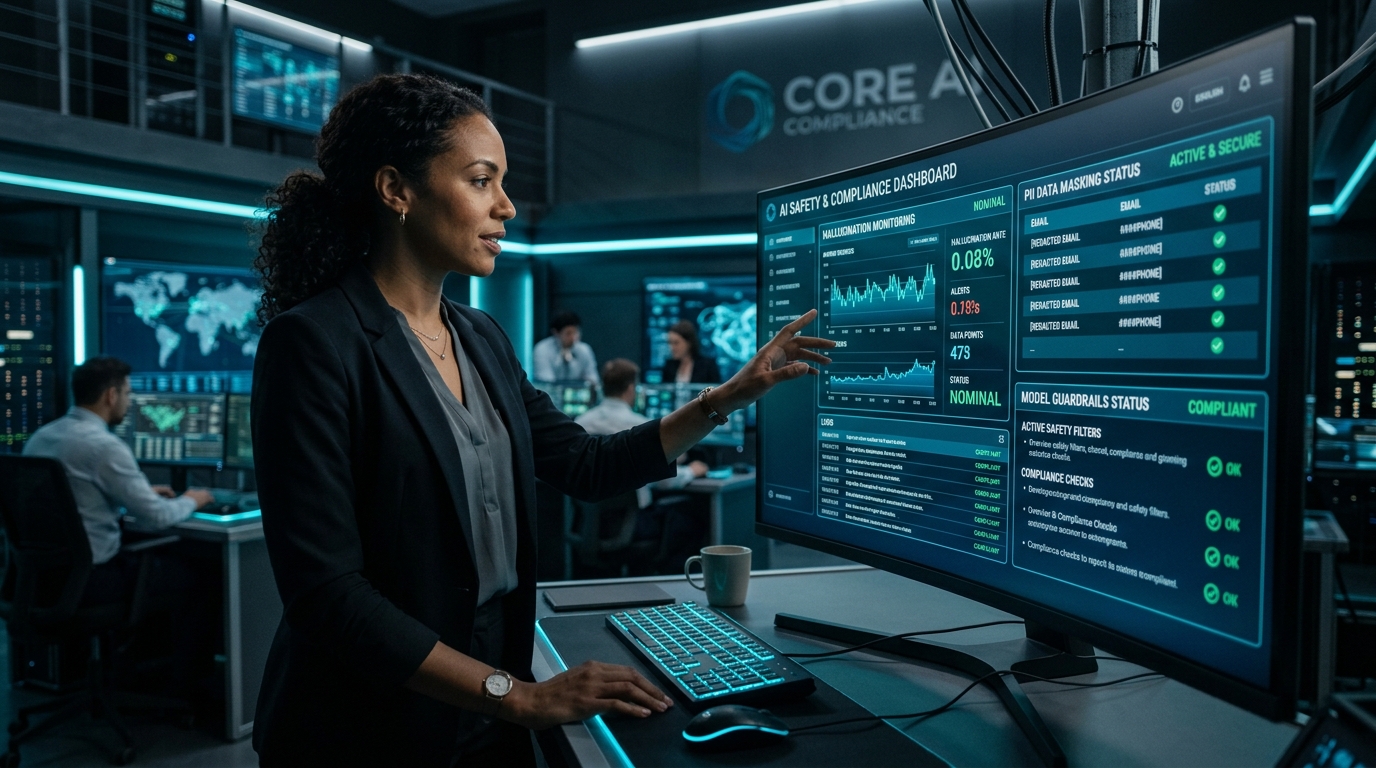
Enterprise Guardrails, Safety & PII Redaction
Deterministic Defense Against Jailbreaks, Hallucinations & Data Leaks
Protect your enterprise reputation and customer trust. We build deterministic guardrail layers that redact sensitive PII, prevent prompt injection attacks, enforce brand guidelines, and ensure SOC2/HIPAA compliance.
- Automated PII masking & tokenized data anonymization
- Real-time prompt injection & adversarial jailbreak filters
- Fact-checking verifiers for hallucination detection
- Role-based token rate limits & corporate spend caps
- Comprehensive regulatory audit logging & compliance reports
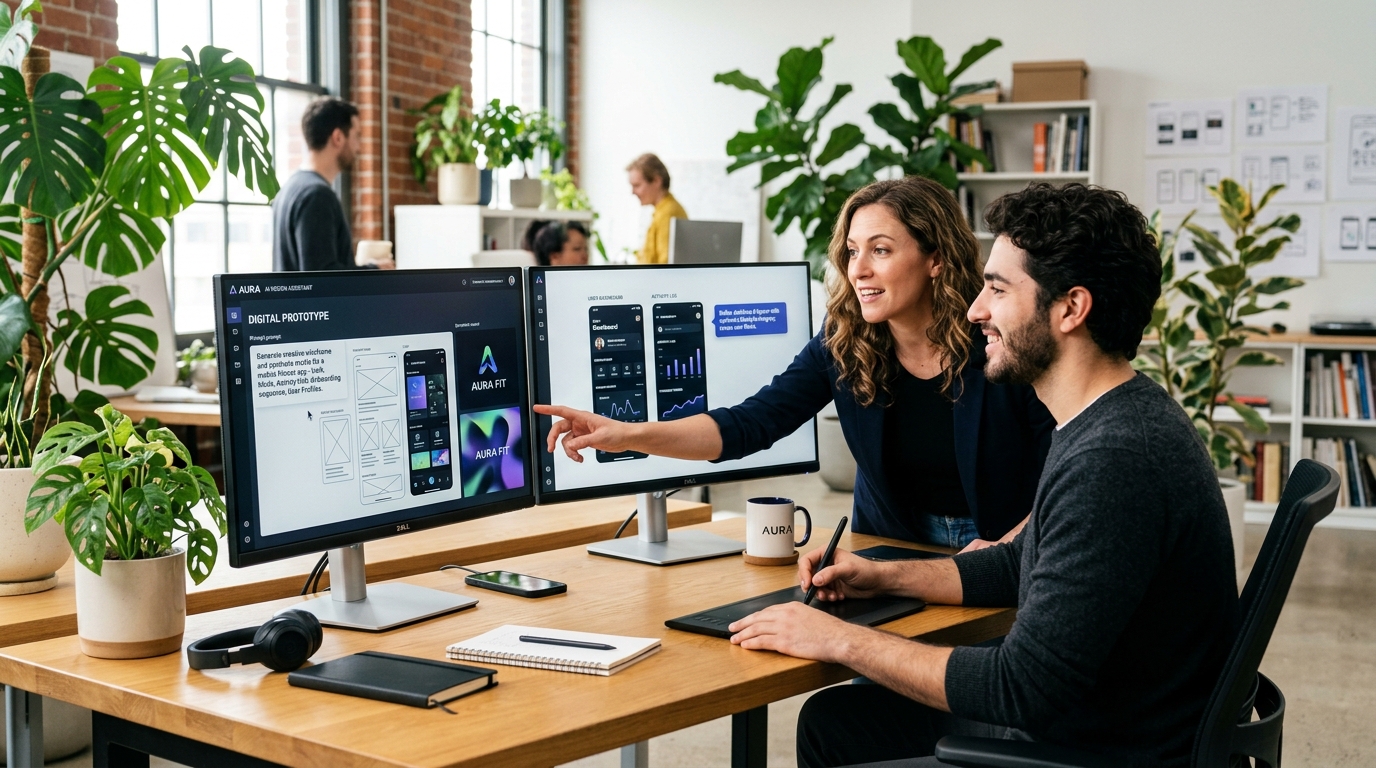
Generative Product Design & Creative Co-pilots
Augment Product Designers & Creators with Generative Intelligence
Empower your design, content, and engineering teams with contextual co-pilots that accelerate wireframing, synthetic asset generation, localized variant generation, and creative prototyping in record time.
- AI-accelerated UI prototyping & design variant generation
- Dynamic personalization of website copy & imagery
- Automated marketing asset generation within brand rules
- Natural language to code and mockup transformations
- Interactive co-pilot plugins for everyday team software
Model Fine-Tuning & Domain Adaptation
Customizing Open-Source & Proprietary Weights for Peak Accuracy
When prompt engineering isn't enough, we fine-tune open-weight models (Llama 3, Mistral, Qwen) using LoRA and QLoRA on your private domain vocabulary, delivering superior task precision at up to 70% lower inference cost.
- Dataset curation, deduplication & synthetic data generation
- Efficient LoRA / QLoRA parameter-efficient fine-tuning
- Self-hosted model inference engines (vLLM, Ollama, TensorRT-LLM)
- Strict data isolation ensuring training data remains private
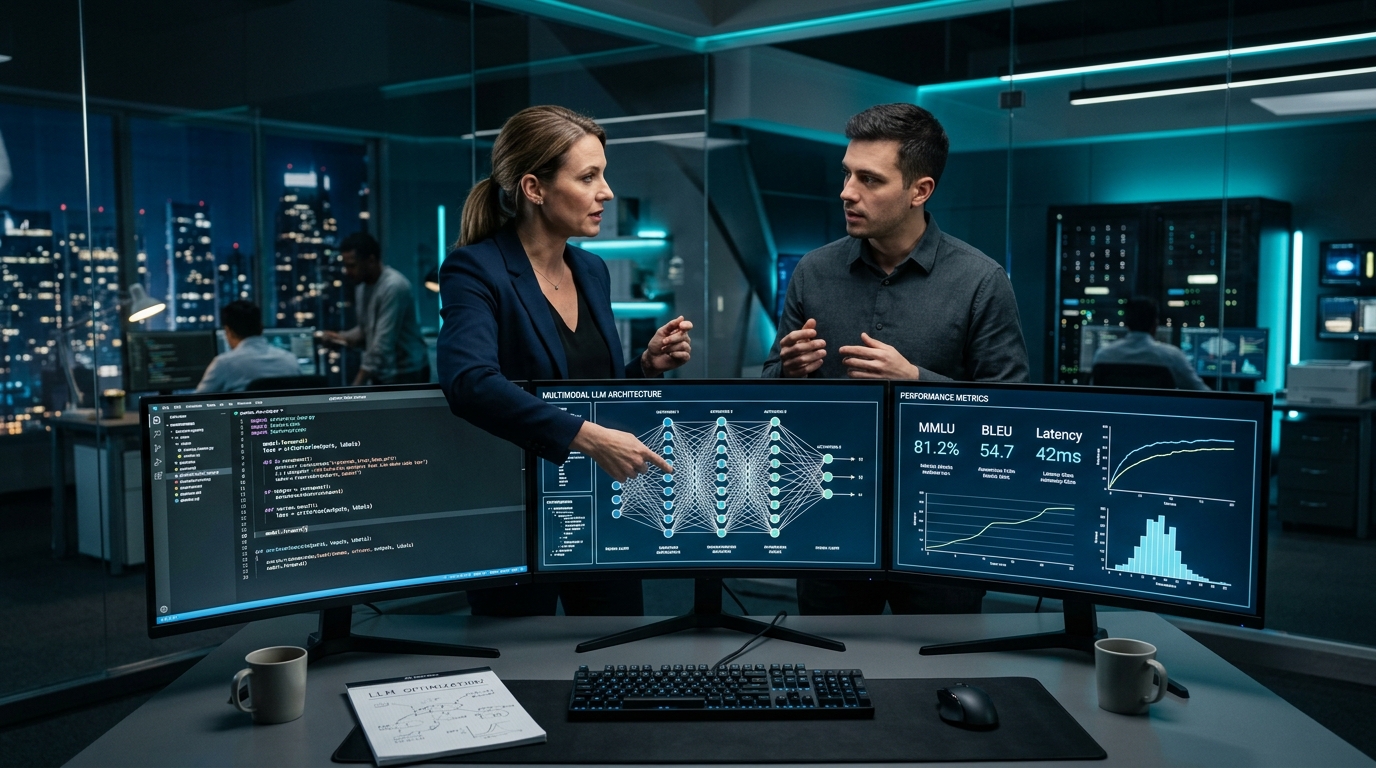
- Head-to-head MMLU and custom domain benchmark validation
Prompt Engineering & Pipeline Optimization
Deterministic Structured Outputs with Minimized Latency & Cost
Turn erratic natural language prompts into deterministic, production-grade pipelines. We craft few-shot prompt libraries, dynamic contextual templates, and strict JSON Schema validators for rock-solid software integration.
- Few-shot, chain-of-thought, and self-consistency prompt architectures
- Strict JSON Schema & Zod output validation enforcement
- Token economy optimization reducing recurring API costs by 40-60%
- Latency reduction via streaming responses & parallel tool calls
- Automated prompt regression testing & continuous evaluation suites
Transforming Customer Experience with Human-Grade AI Interaction
Generic chatbots frustrate customers with circular robotic loops. Our generative AI customer experience platforms are designed like skilled concierge specialists: thoughtful, fast, accurate, and completely aligned with your brand voice.
Sub-Second Streaming Responses
Instant token streaming keeps users engaged with zero perceived loading lag.
Dynamic Contextual Memory
Maintains multi-turn context across sessions, remembering user preferences and history.
Frictionless Human Escalation
Detects frustration and smoothly hands off the full chat transcript to live team members.
100% Brand Voice Consistency
Enforces strict tone, terminology, and compliance standards across every customer touchpoint.
Beyond Simple Prompts: Multi-Agent Autonomous Swarms
Single-prompt AI systems fail when tasks require multiple steps, external data lookups, code execution, and quality audits. We build multi-agent networks where specialized AI agents collaborate just like human engineering teams.
Research & Data Ingestion Agent
Queries internal databases, vector stores, and external APIs to gather pristine facts.
Reasoning & Synthesis Agent
Processes gathered facts, evaluates business rules, and drafts actionable solutions.
Tool Execution & System Sync Agent
Executes verified REST API calls into your ERP, CRM, billing, and communication systems.
Quality Assurance & Hallucination Auditor
Cross-checks drafted outputs against ground truth before anything is shown or sent.
Zero Data Leakage, Zero Unauthorized Disclosures
Deploying generative AI without robust guardrails exposes your business to regulatory penalties, data exfiltration, and brand liability. We implement multi-layered defenses that enforce safety deterministically.
Real-Time PII & Sensitive Token Redaction
Customer names, credit card digits, Social Security numbers, and confidential keys are scrubbed before payload transmission.
Adversarial Prompt Injection & Jailbreak Defense
Input classifiers intercept malicious override commands, indirect injection attempts, and exfiltration prompts.
Factual Grounding & Hallucination Scoring
Every synthesized sentence is verified against retrieved vector chunks. Low-confidence assertions are automatically blocked.
Immutable Telemetry & Access Audit Logging
Full token lineage, user sessions, prompt histories, and safety checks are archived to satisfy enterprise compliance audits.
Structured 6-Phase Generative AI Engineering Process
We take an iterative, de-risked approach from business feasibility mapping to high-scale production deployment.
Opportunity & ROI Mapping
We identify your highest-leverage business use cases, evaluate data availability, model requirements, and project measurable ROI before writing code.
Knowledge Pipeline Setup
Audit, clean, and chunk internal knowledge bases, technical manuals, and databases. We implement hybrid semantic indexing and vector storage.
Interactive Working Prototype
Build an interactive functional prototype connecting the chosen foundation models, vector stores, and custom prompt templates for real evaluation.
Safety, Security & Interface
Implement deterministic security guardrails, PII redaction, prompt injection defense, and an intuitive customer-facing or internal user interface.
Human-in-the-Loop Testing
Run rigorous synthetic benchmark tests and pilot user trials. We fine-tune prompts, adjust retrieval parameters, and optimize token efficiency.
Deployment & Scaling
Deploy to cloud or private infrastructure with auto-scaling, latency caching, token spend caps, error telemetry, and ongoing model monitoring.
Generative AI Engineered for High-Impact Sectors
Explore how tailored generative models and private knowledge grounding transform workflows across enterprise verticals.
Clinical Document Synthesis & Patient Assistants
Accelerate medical chart review, summarize complex lab results, and provide patient-facing intake assistants grounded strictly in verified clinical guidelines.
Regulatory Intelligence & Automated Risk Audits
Synthesize earnings transcripts, conduct automated anti-money laundering triage, and query complex policy manuals with deterministic reference citations.
Generative Product Discovery & Style Advisors
Create interactive shopping concierges that understand nuanced customer intent, generate personalized product recommendations, and boost checkout conversions.
Contract Analysis & Legal Research Copilots
Extract indemnity clauses, compare vendor contracts across thousands of pages, and generate first-pass legal briefs with exact paragraph citations.
In-App AI Copilots & Natural Language Querying
Upgrade your SaaS platform with native generative capabilities: natural-language-to-SQL analytics, automated report generation, and intelligent assistant modals.
Technical Manual Querying & Maintenance Assistants
Equip field service engineers with multimodal AI assistants that diagnose equipment failures from photo uploads and technical machinery schematics instantly.
Frequently Asked Questions
Clear, technically grounded answers regarding enterprise generative AI architecture, security, model training, and integration.
Generative AI development is the practice of engineering custom applications, software features, and automated workflows that use generative foundation models (LLMs, multimodal AI) to understand context, generate human-grade content, assist users, and execute complex business processes with verifiable grounding.
We implement Retrieval-Augmented Generation (RAG) and deterministic verification guardrails. The AI model is strictly instructed to answer only using retrieved factual passages from your enterprise knowledge base. If information is missing, the system gracefully acknowledges it rather than guessing. Exact citation links are attached to every statement.
No. We enforce strict data privacy protocols. When using enterprise APIs (such as Azure OpenAI, AWS Bedrock, or private Anthropic endpoints), your data is never logged or used for model training under strict enterprise agreements. For sensitive deployments, we also deploy self-hosted open-weight models (like Llama 3) inside your private cloud VPC.
A chatbot simply responds to messages. An autonomous AI agent is goal-oriented: it breaks down multi-step tasks, reasons through problems, calls external APIs (like updating a CRM, querying an inventory database, or sending an email), verifies its own outputs, and operates with supervisory approval gates.
Yes. We specialize in building seamless integrations into existing Next.js, React, mobile apps, ERPs, CRMs, and SaaS products. We deliver clean REST / WebSocket APIs and modular UI component libraries that slide effortlessly into your existing tech stack.
We optimize token consumption through semantic prompt caching, concise system prompts, intelligent model routing (directing simpler queries to faster, cost-effective models and reserving heavy reasoning for flagship models), and token rate limits, typically reducing cloud API expenses by 40% to 60%.
A focused Proof of Concept (PoC) or functional MVP typically takes 3 to 5 weeks. A full-scale enterprise AI platform with enterprise vector databases, multi-agent pipelines, custom security guardrails, and third-party integrations usually takes 8 to 12 weeks.
Yes, 100%. All custom code, proprietary prompt libraries, fine-tuned model weights, vector database pipelines, and documentation developed during your engagement belong entirely to your company.